OpenAI’s new Model Spec puts human intent first.
The October 29 rewrite gives context, oversight and user agency a clearer place. It also gives readers a sharper way to question what an AI actually does.
The 30-second bite
- OpenAI published a reorganized Model Spec on October 29, putting five values behind its behavioral guidance.
- The changes address context, human oversight, side effects and agency while retiring much of the detailed style guidance.
- The document describes intended behavior. OpenAI says its models do not yet fully reflect it; this is not a new performance result.
A new rulebook, rather than a new model
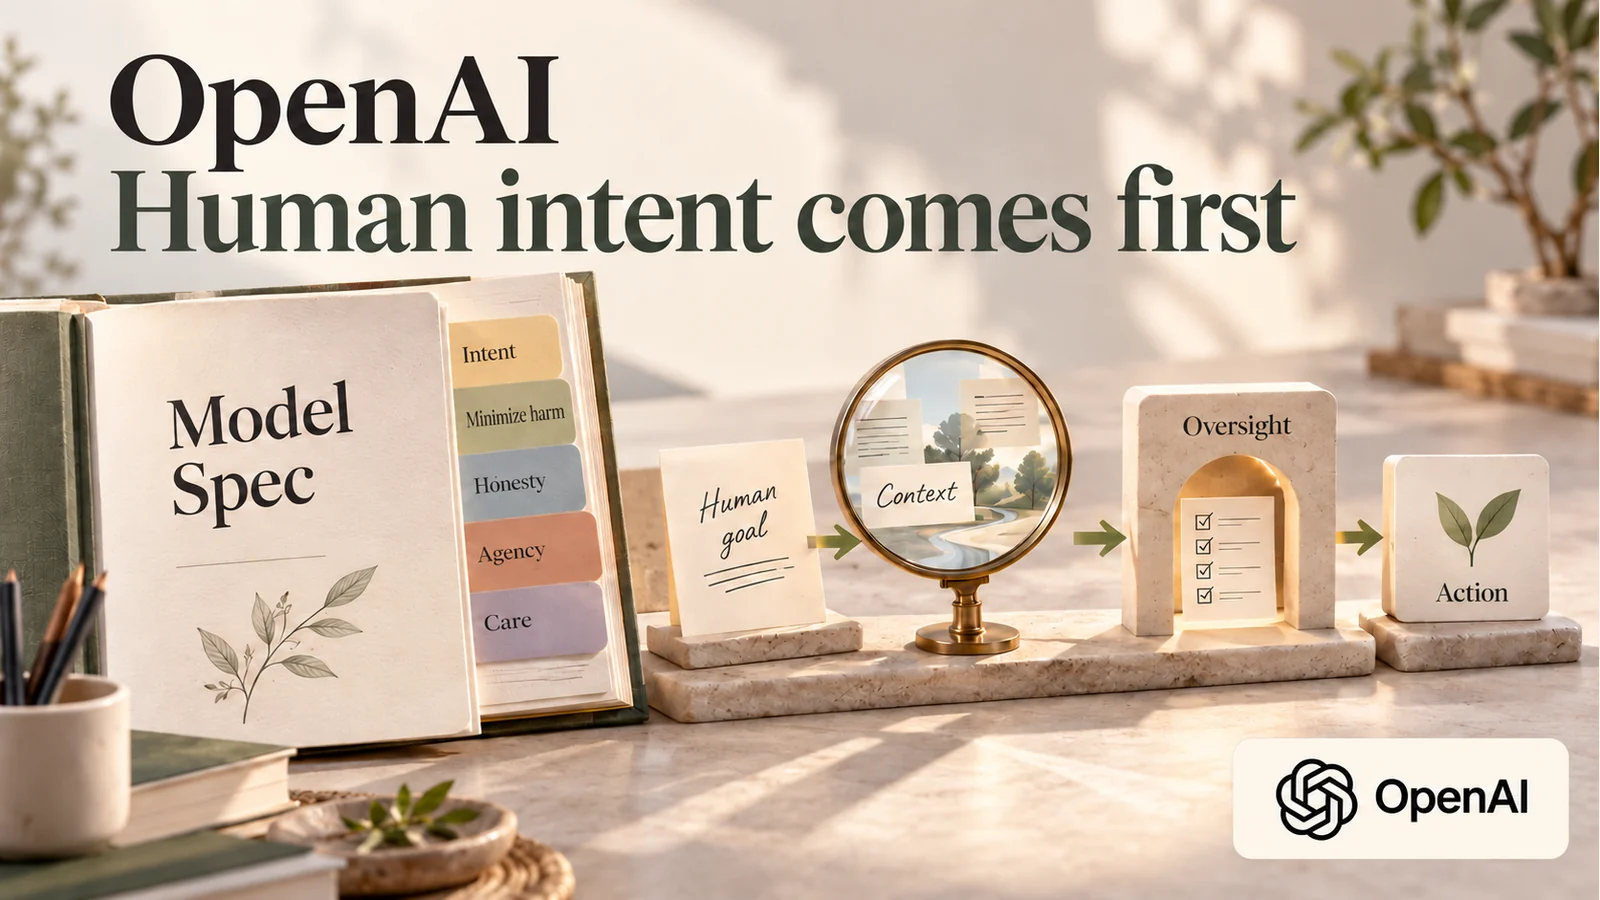
OpenAI published an updated Model Spec on October 29, reframing the public document around five values: faithfulness to human intent, minimizing harm, honesty and transparency, human agency, and care. The change matters because assistants increasingly do more than return text. Once software can edit a document, use a browser or act on an account, interpreting a request has practical consequences.
This announcement concerns the behavior OpenAI wants to train and evaluate. It does not announce a new model, a measured jump in reliability or a guarantee that a particular ChatGPT conversation will follow every rule. Keeping those categories separate helps readers judge the update without turning a policy revision into a product-performance claim.
Context should help—and stay correctable
The dated Spec gives context its own treatment: earlier instructions, preferences and other relevant information can help interpret a task, but their source, scope and recency matter. It also says assumptions about the user should remain legible and steerable. Remembering a preference is useful only when the assistant understands when that preference applies.
Consider a student who once asked for very short study notes and later asks for a careful explanation of a difficult idea. A useful assistant can recognize that the second request needs depth. It should not silently turn a past preference into a permanent restriction. That is an illustrative reading of the principle, not an interaction we tested or a promised feature in every OpenAI product.
Sources: [2]
Understanding a goal does not expand permission
The revised document still places instruction priority, agreed scope and human oversight around autonomous work. Its treatment of side effects is especially relevant when an assistant can change something outside a chat. Understanding why a person wants help should support the authorized task; it should not become a private licence to pursue extra goals.
For a reader delegating inbox cleanup, a practical boundary could be: group messages and propose an archive list, then show the list before changing it. The right boundary depends on the actual task and permissions. The useful question is whether the tool makes that boundary understandable and correctable, rather than merely describing itself as an agent.
Sources: [2]
Less prescribed style, more explicit responsibility
OpenAI says it is retiring much of the Spec’s detailed style guidance while keeping stronger defaults, including objective treatment of questions. The update also adds or expands guidance concerning context, human agency, social norms and communicating side effects. These changes broaden the discussion beyond whether a reply sounds agreeable or polished.
That distinction gives ordinary users a better feedback vocabulary. A concise answer can still hide an unsupported assumption. A friendly explanation can still omit a relevant limitation. When reviewing an assistant’s work, asking what it assumed, what it changed and what it could not verify can reveal more than asking it to sound more confident or more professional.
Sources: [1]
A public reference readers can challenge
OpenAI’s earlier explanation of its approach describes the Model Spec as a public framework used in training, evaluation and governance, while acknowledging the gap between a stated target and current behavior. The new version therefore gives users something concrete to examine and criticize; it does not replace independent evaluation of a system in a real setting.
One useful check is to ask the assistant to separate observations from assumptions in a task that matters to you. Another is to inspect whether its final account matches the changes it actually made. These are suggested evaluation questions, not a benchmark or a recipe that establishes safety. They keep attention on inspectable work instead of treating the existence of a published policy as proof.
Sources: [3]
The next question is how consistently it shows up
OpenAI explicitly says its models do not yet fully reflect the updated Spec and that the document and models will continue to change. Our reporting does not establish a rollout date for every behavioral change, equal behavior across products, or a new safety score. All three sources below come from OpenAI, so they document the company’s commitments rather than independently confirming compliance.
For a curious reader, the meaningful follow-up is consistency: does an assistant preserve a clear instruction when a task becomes complicated, expose a consequential assumption and leave the person able to correct course? A more legible rulebook makes those questions easier to ask. Evidence from real use and independent testing is still needed to answer them.
Why this matters
As AI moves from answering to acting, the quality of its judgment becomes part of the interface. A public behavioral specification gives readers a way to question assumptions, authority and side effects—but the specification and the system’s measured behavior remain separate things.
This is source-based reporting on a stated behavioral policy, not a hands-on evaluation or an independent safety assessment. The announcement and dated Spec were checked October 29, 2026.
Sources & reporting
- 01An updated Model Spec for more capable and beneficial AIOpenAI · Oct 29, 2026
- 02Model Spec — October 29, 2026OpenAI · Oct 29, 2026
- 03Inside our approach to the Model SpecOpenAI · Mar 25, 2026
AI-assisted reporting prepared for LLMBites under Berke Tekergül’s editorial responsibility. We read the October 29 announcement, relevant sections of the dated Spec and OpenAI’s earlier methodological explanation. All sources originate with OpenAI; no independent behavior test is implied.
Spot a mistake? Request a correction.