One AI training opt-out is coming, but answer controls still differ
Google, Microsoft and OpenAI have backed a common website training preference. Their timelines and separate rules for AI answers matter before publishers change robots.txt.
 The 30-second bite
- An October 30 draft proposes one shared robots.txt preference for AI training across participating providers.
- Google, Microsoft and OpenAI describe future support, not a proven cross-provider block today.
- Training, crawling and using a page to ground an AI answer remain separate questions.
- Microsoft's NoArchive and NoCache transition gives some publishers a March 1, 2027 action date.
One line, but not one blanket permission
A small publisher may soon be able to express an AI training choice once in robots.txt rather than maintaining a separate rule for each participating provider. That is the concrete change Google, Microsoft and OpenAI endorsed on October 30. The important condition is timing: their common signal is a proposal and future implementation, not a switch that has already been verified to work across all three services.
The proposed line uses the policy token __usage_ai-training. In a conventional robots.txt group, a site owner could pair that User-Agent token with Disallow: / to express a preference against AI training for the whole site. This is an illustrative example from the draft, not a configuration LLMBites deployed or tested. It tells a participating service what use the publisher opposes; it does not grant a technical ability to claw back data already collected or prevent every possible use of the page.
What the proposed signal actually says
The draft defines AI training narrowly: using a piece of content to change the learned parameters of a generative model. It reuses ordinary robots.txt Allow and Disallow syntax, so the novelty is a shared purpose label rather than a new file format. The document is an individual Internet-Draft. The IETF tracker explicitly says it is not endorsed by the IETF and has no formal standing in its standards process. Calling it an adopted internet standard today would overstate the evidence.
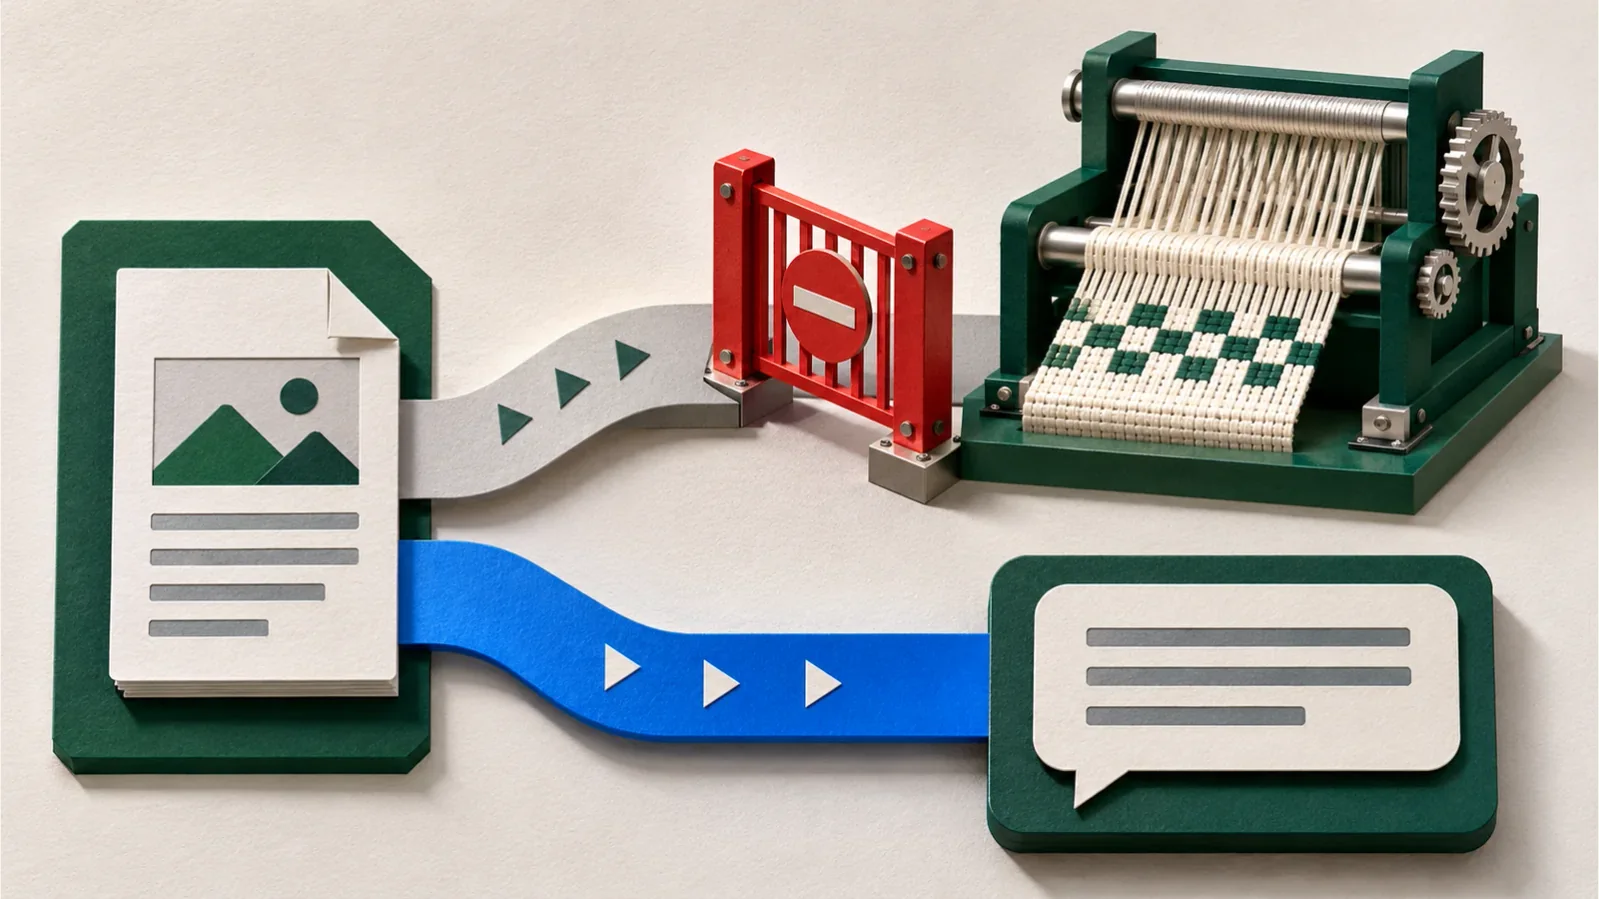
A separate crawler rule still matters. The draft says this training token is not a directive to stop fetching pages. Its own example distinguishes a service's crawler identity from the publisher's preference for how retrieved content is used. A site that wants to limit crawling would still need to examine the relevant crawler controls. A preference is also not a guarantee that every company, dataset or private arrangement will behave the same way.
Training and AI answers are different decisions
Imagine a local news site that wants its articles discoverable and cited when an assistant answers a reader, but does not want those articles used to train future generative models. The training preference addresses the second use. It does not, by itself, settle whether an AI product may retrieve and use a page while composing an answer, often called grounding. That distinction is the practical decision a publisher should make before editing a rule file.
Microsoft makes the split explicit in its announced controls. It says publishers will be able to disallow training yet allow grounding, with grounding set per page. Google describes a different coupling: when no Google-Extended preference is explicitly present, it plans to interpret the shared training opt-out as a Google-Extended disallow. Google says a specific Google-Extended allow can preserve eligibility for grounding in Gemini Apps. These are provider plans, not an independent test of the final behavior.
The dates determine what to do now
Google says it aims to support the shared control in 2027. OpenAI says it aims to honor the signal in the coming months and will publish more implementation detail later; its existing crawler controls remain in place. Microsoft gives a more specific date: February 1, 2027, as it crawls pages. None of those statements establishes that a shared-token edit made today is already enforced across providers. Search Engine Journal's separate comparison reaches the same timing caution from the announcements; it is reporting, not an enforcement experiment.
Microsoft has an extra transition problem for sites relying on NoArchive or NoCache. It says those older tags will stop being honored as training or grounding preferences after March 1, 2027. For continued grounding restrictions, affected sites must publish the new page preference and record a temporary setting in Bing Webmaster Tools by that date. A page's new setting still depends on recrawling. That is a reason to audit existing rules before replacing them, not a reason for every casual website owner to rush into a migration today.
A useful publisher checklist
First, decide which outcome matters: preventing future training, limiting AI-generated answers, limiting crawls, or some combination. They are not interchangeable. Next, list the provider-specific controls already in your robots.txt and page metadata. In particular, check for Microsoft NoArchive or NoCache use and for any explicit Google-Extended rule before assuming the common line will have a uniform effect. Finally, record the providers' actual activation dates and check their current documentation again when those dates arrive.
For a reader who does not operate a website, the distinction matters too. A page appearing in an AI answer is not evidence that it trained the underlying model; an opt-out from training is not necessarily an opt-out from answer grounding. Conversely, the existence of a new preference does not prove anyone complied with it. The measure of this announcement will be implementation details and observable behavior after rollout, not the number of companies named in the launch.
Why this matters
One common preference could reduce the work of managing provider-by-provider training rules, but website owners need to choose separately what they want to happen to AI answers and crawling. The announced rollout is gradual and provider-specific.
The shared signal is an individual Internet-Draft, not an IETF-approved standard. Provider posts describe planned support. LLMBites has not deployed the token, observed any crawler honoring it, or verified downstream use of site content. Existing controls and contracts may differ.
Sources & reporting
- 01Machine-Readable Training Preference Signal, draft-kelley-aipref-training-preference-signal-00IETF Datatracker / Kevin Kelley · Oct 30, 2026
- 02Supporting a shared AI training control for websitesGoogle Search Central · Oct 30, 2026
- 03Your content, your choice: clearer preferences for training and groundingMicrosoft Bing Blog · Oct 30, 2026
- 04Making it easier for websites to express AI training preferencesOpenAI · Oct 30, 2026
- 05Google, Microsoft & OpenAI Plan To Honor Shared AI Training Opt-OutSearch Engine Journal · Nov 1, 2026
AI-assisted research and drafting. AI assisted research and drafting from the full IETF draft, Google, Microsoft and OpenAI announcements, and Search Engine Journal's independent comparison. That comparison analyzes the announcements rather than independently testing enforcement. The configuration example and publisher checklist are explanatory analysis, not hands-on results. No human interview or pre-publication human review was conducted. Automated editorial and visual checks were performed by the writing agent; this article did not receive pre-publication human or independent editorial review.
Spot a mistake? Request a correction.